UniverSat: Resolution- and Modality-Agnostic Transformers for Earth Observation
Published in NeurIPS, 2026
Recommended citation: Perron Y. (2026). "UniverSat: Resolution- and Modality-Agnostic Transformers for Earth Observation" NeurIPS. https://arxiv.org/pdf/2606.23503.pdf
Yohann Perron - Guillaume Astruc, Nicolas Gonthier, Clément Mallet and Loic Landrieu
PDF - Code - Demo - Project Page
Abstract
Vision Transformers (ViT) dominate computer vision. However, their reliance on rigid patch projectors hinders transfer to Earth Observation (EO), where input modalities, scales, and resolutions vary widely. We introduce UniverSat, a ViT-style backbone built around a Universal Patch Encoder that maps patches from arbitrary spatial, spectral, and temporal resolutions, and from both optical and non-optical sensors, into a shared embedding space with a shared set of weights. This enables training a single model on heterogeneous multimodal corpora via self-supervision, yielding robust, sensor-agnostic spatial features. We validate this approach with strong results across classification and segmentation on standard EO benchmarks from GeoBench, PANGEABench, and SpectralEarth.
Keywords
- Modality-Agnostic
- Multi modalities
- Modalities fusion
- Satellite Times Series
- Self-supervised learning
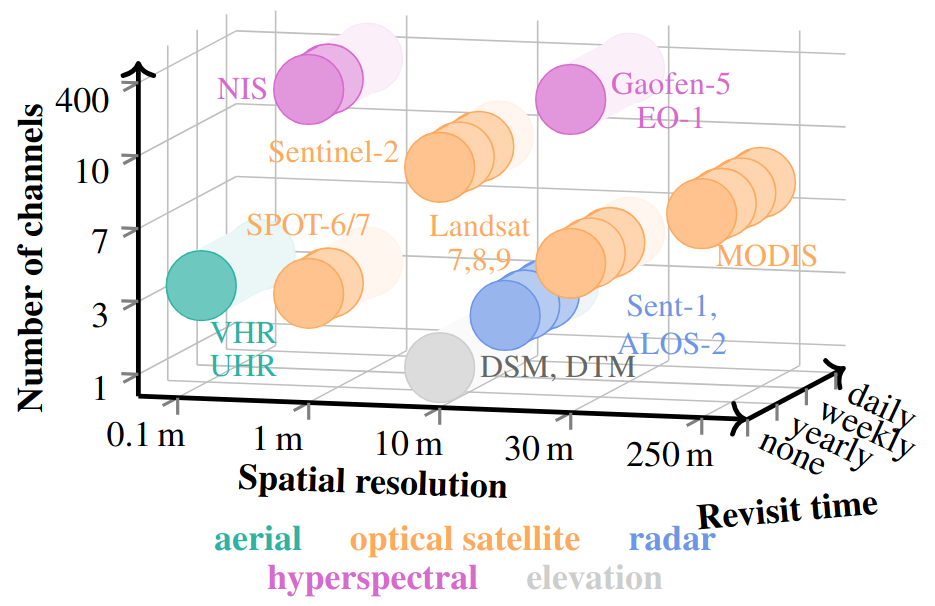
Overview of the training dataset :
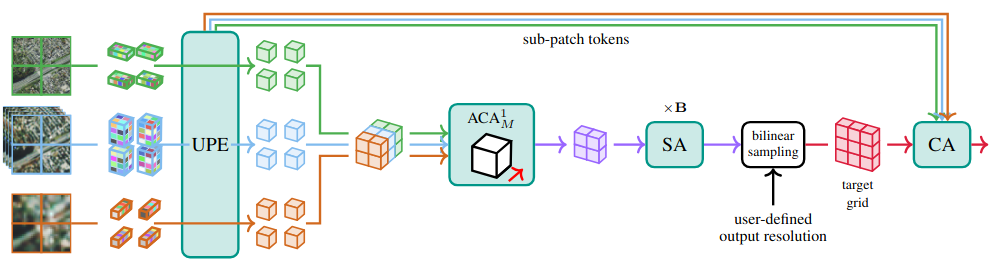
Architecture of the UniverSat model :
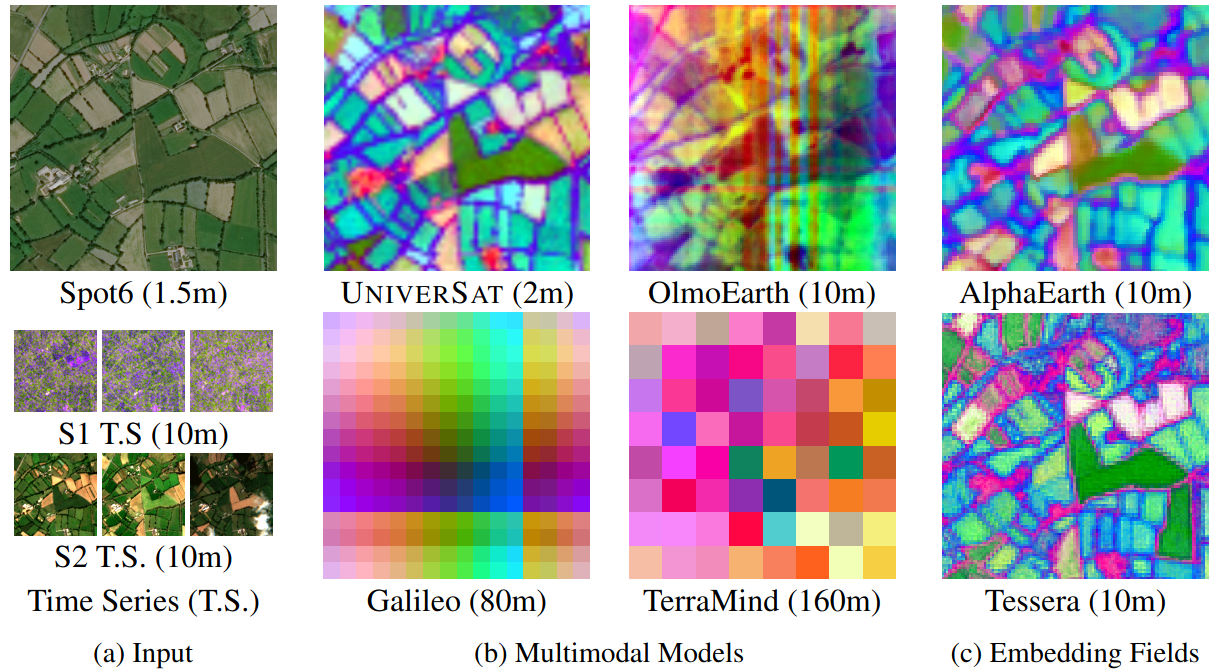
PCA projections of features from a multimodal PASTIS test tile. UniverSat preserves field boundaries and fine spatial structures at higher granularity than competing multimodal models.